You can block ClaudeBot in robots.txt in two lines. Blocking the crawler behind the search index that AI answers may draw on is harder, because that crawler has no name to type.
The New York Times sued Brave Software on November 2, 2026. In its complaint the Times says Brave copied content from over 30 billion webpages without identifying itself or giving site owners any way to block its crawler. Brave's own crawler page agrees on the first point: it does not advertise a separate user agent.
My read: robots.txt rules aimed at one AI company's bots are a weak control for AI search. The index behind the answers is a different system with different rules.
The case is mostly about copyright. The Times filed it in federal court in Manhattan as Civil Action No. 26-cv-9549, and one paragraph in it matters to anyone who manages crawler access. Paragraph 2 of the Times's complaint says: "Brave crawled and copied content from the over 30 billion webpages in the Brave Index without identifying itself or providing website owners with any mechanism to block its crawler."
The Times also says Brave sells what it copies. The complaint describes Brave as the supplier of stolen copyrighted content to AI companies, including Anthropic, Perplexity, Mistral, xAI and Cohere. A separate complaint names the Daily News, Chicago Tribune and Orlando Sentinel as plaintiffs against Brave. Reuters reported that Brave sued News Corp in March 2025 and that News Corp filed a countersuit in July 2026.
New York Times spokesperson Graham James gave The Verge the company's position: "While we believe in the ethical and responsible use and development of AI, Brave has flouted established copyright law and ignored repeated requests by The Times to stop its infringing conduct"
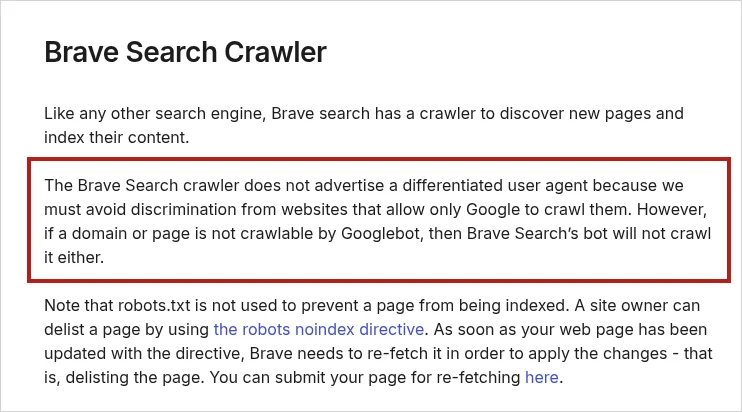
Brave's crawler page explains the missing name: "The Brave Search crawler does not advertise a differentiated user agent because we must avoid discrimination from websites that allow only Google to crawl them."
The same Brave page sets the one crawl rule Brave documents. If a domain or page cannot be crawled by Googlebot, Brave says, its bot will not crawl it either.
A publisher who wanted to keep Brave's bot out through robots.txt would have to disallow Googlebot as well. That Google search trade-off rules it out for most publishers.
The page adds that robots.txt is not used to prevent indexing. A noindex directive delists a page once Brave re-fetches it.
The Claude connection
The suit reaches past publishers because of how Claude finds pages. Merj, a technical SEO consultancy, reports that Google Cloud's documentation for Anthropic's models says Brave Search does the searching when Claude searches the web. Merj also cites an analysis of roughly 35,000 Claude citations by Profound, an AI visibility vendor. In that sample, 79.2% of the cited URLs appeared in Brave's top 10 for the matching query, against 34% for Google's top 10. That is one vendor's sample, relayed by Merj.
Merj's reading of Brave's own tooling covers the other half. It says Brave has no search console, no sitemap submission and no IndexNow. There is no front door to knock on.
The switch is not where the advice puts it
My read is that the Claude line in your robots.txt does less than people think. It asks Anthropic's own crawlers to stay out. If Merj has the plumbing right, many of the pages Claude can cite come from an index built by a bot with no name, no console and one documented crawl rule. Brave need not be Claude's only route to a page. This is a gap in control, and it is not proof of what Claude cites.
By Brave's own documentation, Googlebot access is a condition for its bot to crawl a page, and noindex is how a page leaves. Neither is a Claude setting.
I can't tell you whether the Times will win. The case shows a gap between two things people treat as one: telling a company's named crawlers to stay out, and controlling the index that company's search draws on. A robots.txt line handles the first. For the second, the levers Brave documents are Googlebot access and noindex.
Free newsletter
The Sherpa Brief
One email a week on what changed in AI search, what it means, and what to do about it. Written for marketers, SEOs, and publishers.
Free. Unsubscribe in one click.