You set Cloudflare's Search policy to Allow because you want Google in. You set Training to Block because you want the AI labs out. Then you assume Googlebot is fine.
Seven weeks after Cloudflare added a Disallow option to protect Googlebot, two site owners say Block still locks it out. One posted on Reddit on November 7, the other on Cloudflare's forum a day earlier. Both had Search on Allow. Cloudflare's AI crawler documentation defines Training as "crawlers taking your content to train or fine-tune a model, including mixed-purpose crawlers that are used both for Training and for Search."
My read is that a site Googlebot cannot fetch has no way into AI Overviews or AI Mode. If these reports hold up, the setting meant to limit AI use can take you out of Google's AI answers.
The forum report came first. A site owner posting as fixated93 said Search Console could not read the sitemap and returned a 403. The forum thread is dated November 6.
The owner pointed to Cloudflare's security logs. "Cloudflare Security Events confirms that Googlebot (Google LLC, AS15169) was blocked while requesting /sitemap.xml. The matching security rule was "Block AI training crawlers." My Cloudflare AI crawler settings already allow Search crawlers, but Googlebot was still blocked."
A forum member named gluonplasma answered that this is the design. "setting AI training to "block" literally blocks all bots that do scraping and training on your site content, that includes googlebot and bingbot, so it is working as intended."
The documentation reads the same way. It describes Block as an action that blocks matching requests across the zone. It also says Training actions apply to mixed-purpose crawlers used for both Search and Training.
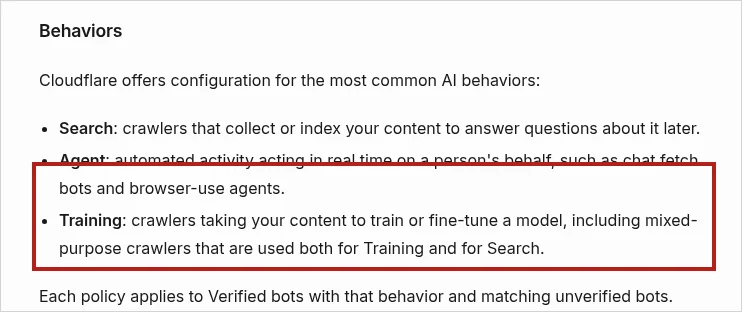
Cloudflare does not name Googlebot on that page. The link to Googlebot is the owners' reading of their logs.
The Reddit report a day later
On November 7, a poster named iam_batman27 put the same story in r/SEO, r/CloudFlare and r/TechSEO. After digging through the security logs, the poster found the rule was "actually blocking Googlebot." Search was set to Allow, and the Training setting was set to Block.
The poster says the repair was Search on Allow, Training on Disallow and Bot Preference Sync switched on. After that, Google's Live URL Test reportedly worked for the homepage and the sitemap.
That matches what Cloudflare changed in September. Search Engine Journal reported on September 15 under the headline Cloudflare Lets Sites Disallow AI Training Without Blocking Googlebot. The fix applies to Disallow. These two owners say they were on Block.
Disallow has its own catch. The documentation says it tells training crawlers to stay away through robots.txt. With Bot Preference Sync on, it also blocks them at Cloudflare's edge, and mixed-purpose crawlers are excluded from that edge block. For those crawlers, your opt-out rests on robots.txt and Google's own controls.
Those controls carry a trade. SEO consultant Alex Groberman wrote on November 1: "Worth keeping in mind - Google-Extended can be disallowed without affecting Google Search rankings, but Google says that control also affects whether your content can be used for grounding in Gemini Apps." He had also warned the same day that "If you select Block for Training, mixed-use crawlers including Googlebot, Bingbot and Applebot can now be blocked completely, including their Search access."
Not everyone sees a systemic fault. A user posting as ConsciousRide replied on X on November 1 that it was one reported incident. "This is one reported incident, so I wouldn't call it a widespread Googlebot issue. But it raises a question worth checking on your own website: how many access rules are currently active that you never explicitly chose?"
A commenter on r/CloudFlare, u/panlazy, raised a different point. The commenter says the rule may have caught a client that only claimed to be Googlebot. "Two things can both be true here: the rule hit a client that really was Googlebot, or it hit something that merely said it was. Worth checking which one happened in your logs, because the fix differs." The commenter discloses working on IPScanner, a verified-crawler product.
I could not run the reverse DNS check on the forum poster's IP address, and I cannot tell you these requests were authentic Googlebot. The owners say they were. Their logs name Google LLC and AS15169.
Disclosure: AEO Sherpa runs on Cloudflare's EmDash CMS.
Where I land
I would not call this widespread. Two owners is two owners. What bothers me is the naming. Search, Training, Block and Disallow sound like separate dials, and an owner who sees Allow next to Search has little reason to open the logs.
Treat the Training setting like a robots.txt file. A single line in either place can cut a site out of Google, and the AI answers that draw on Google's index go with it. Until the documentation says plainly that Block reaches Googlebot whatever Search is set to, I treat the Search toggle as unproven.
Free newsletter
The Sherpa Brief
One email a week on what changed in AI search, what it means, and what to do about it. Written for marketers, SEOs, and publishers.
Free. Unsubscribe in one click.